Homelab update: GPU expansion for local AI workloads
The homelab has been extended with an RTX 3090 providing 24 GB of VRAM.
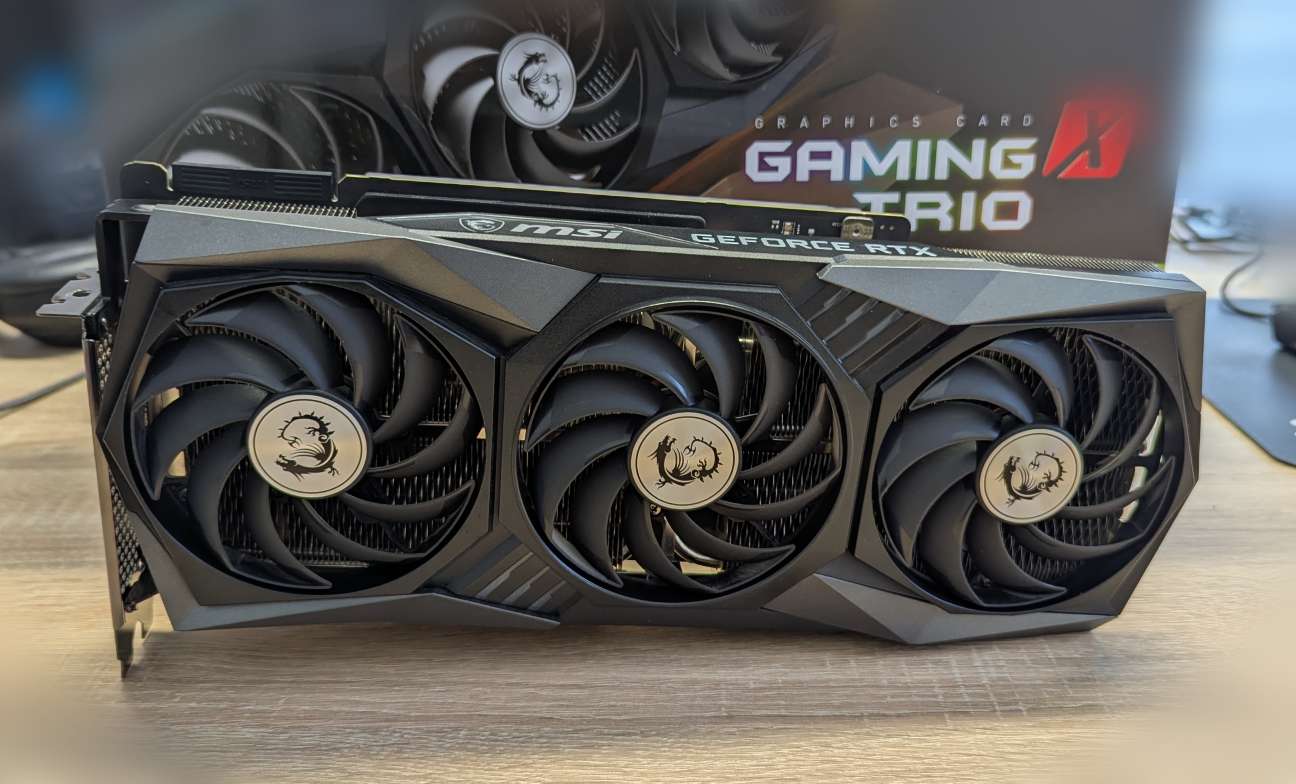
For many AI workloads, VRAM capacity is the binding constraint. This applies to:
- Large language models (LLMs)
- Image generation models
- Embedding pipelines for semantic search
At the same time, GPU prices are climbing again, driven by demand from data centers and AI infrastructure.
The choice of the RTX 3090 reflects price per gigabyte of VRAM rather than recency of the hardware:
- 24 GB of VRAM allows models that do not fit in 12–16 GB to be run without offloading
- CUDA-based tooling works without adaptation
- Considerably cheaper than current-generation high-VRAM cards
The card is passed through to Proxmox VMs and used for the following workloads:
- Embedding generation for semantic document search using FastAPI, Ollama and Qdrant
- Information extraction using Docling
- Image generation with ComfyUI
Further experiments are planned.